
All about robots.txt
What is robots.txt ?
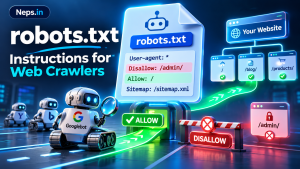
robots.txt is a small plain-text file that sits at the root of a website and gives instructions to search engine crawlers (and other well-behaved bots) about which parts of the site they’re allowed to crawl.
It lives at a fixed, predictable location:
https://www.example.com/robots.txt
How it works ?
When a crawler like Googlebot visits your site, one of the first things it does is check robots.txt to see if there are any crawling rules it should follow.
A basic one looks like this:
User-agent: *
Disallow: /admin/
Allow: /

Sitemap: https://www.example.com/sitemap.xml
User-agent: *— applies to all crawlersDisallow: /admin/— “please don’t crawl anything under /admin/”Allow: /— everything else is fair gameSitemap:— points crawlers to your XML sitemap
List of User-agent
There’s no fixed, closed list of “all possible” user-agents for robots.txt — any crawler can identify itself with any token, and site owners can write rules for wildcards or fictional names. But here’s a practical breakdown:
Special/wildcard tokens
| Token | Meaning |
|---|---|
| User-agent: * | Applies to all crawlers that don’t have a more specific rule |
Common real-world crawler user-agents
Search engines
– Googlebot (general)
– Googlebot-Image, Googlebot-News, Googlebot-Video
– AdsBot-Google, AdsBot-Google-Mobile
– Mediapartners-Google (AdSense)
– Bingbot
– Slurp (Yahoo)
– DuckDuckBot
– Baiduspider
– YandexBot
– Sogou
– Exabot
– facebookexternalhit
– Twitterbot
– LinkedInBot
– WhatsApp
– Applebot
– SeznamBot
SEO/marketing crawlers
– AhrefsBot
– SemrushBot
– MJ12bot (Majestic)
– DotBot (Moz)
– BLEXBot
– rogerbot (Moz)
AI/LLM crawlers (increasingly common to block/allow explicitly)
– GPTBot (OpenAI)
– ChatGPT-User
– OAI-SearchBot
– ClaudeBot
– Claude-Web
– anthropic-ai
– CCBot (Common Crawl)
– Google-Extended
– Bytespider (ByteDance)
– PerplexityBot
– Amazonbot
– Applebot-Extended
Archival
– ia_archiver (Internet Archive Wayback Machine)
Important notes
- Any string is valid — a bot’s operator chooses its own user-agent name; robots.txt has no enforcement mechanism, it’s purely a voluntary convention.
- Case-insensitive matching is typical, and matching is usually by substring/prefix.
- More specific rules override
*— if you define bothUser-agent: *andUser-agent: Googlebot, Googlebot follows its own block, not the wildcard one. - Malicious/scraper bots often ignore robots.txt entirely or spoof common browser user-agents, so it’s not a security control — just a crawling-etiquette signal.
Want me to generate a sample robots.txt (e.g., blocking AI scrapers but allowing search engines)?
The key thing to understand about it
robots.txt is a crawling instruction, not an indexing instruction, and it’s voluntary — it relies on the crawler choosing to respect it.
- Reputable bots (Google, Bing, etc.) honor it.
- Malicious bots and scrapers often ignore it entirely — so it’s not a security or access-control mechanism.
- Blocking a URL in robots.txt stops crawling, but if other sites link to that URL, Google can still show it in search results (just without a proper description, since it never crawled the content). To truly keep something out of search results, you need a
noindextag instead — which actually requires the page to be crawlable so Google can see that tag.
Why it exists ?
It’s essentially a traffic-control tool for your site’s relationship with search engines — helping crawlers spend their time on pages that matter, keeping them out of admin areas, internal search results, or duplicate content, and pointing them to your sitemap.
It’s a small file, but a wrong Disallow rule (like accidentally blocking / or your CSS/JS folders) can quietly tank your entire site’s visibility — so it’s worth getting right and checking periodically in Google Search Console.
What should be in robots.txt ?
A robots.txt file uses a simple set of directives to tell crawlers what they can and can’t access:
Sample content of robots.txt
```
User-agent: *
Disallow: /admin/
Disallow: /cart/
Disallow: /checkout/
Disallow: /*?sort=
Allow: /

Sitemap: https://www.example.com/sitemap.xml
```
Core directives:
User-agent— which crawler the rule applies to (*= all crawlers, or specific ones likeGooglebot,Bingbot)Disallow— paths you don’t want crawled (admin panels, internal search results, cart/checkout pages, staging folders, duplicate filtered/sorted URL variants)Allow— explicitly permits a path, usually used to carve out an exception inside a disallowed folder (e.g., disallow/wp-admin/but allow/wp-admin/admin-ajax.php)Sitemap— absolute URL to your XML sitemap(s); helps crawlers find your sitemap without it needing to be submitted separatelyCrawl-delay— supported by some crawlers (not Google) to throttle crawl speed
What typically gets disallowed: admin/login areas, internal search result pages, filter/sort URL parameters that create duplicate content, staging/dev environments, duplicate print-friendly pages, and internal scripts/cart/checkout flows that have no SEO value.
Important: Disallowing a page in robots.txt stops it from being crawled — it does not guarantee it stays out of the index. If other sites link to that disallowed URL, Google can still index the URL (with no content shown) from those external signals. To truly keep a page out of the index, use a noindex meta tag or header instead — and don’t combine noindex with Disallow, since a disallowed page can’t be crawled to see the noindex tag in the first place.
Case sensitivity in robots.txt
Directive names (field names) are case-insensitive. So Disallow, disallow, DISALLOW, and even DiSaLLoW are all treated the same by compliant parsers (Google, Bing, etc.). The convention/most common style is capitalized: User-agent, Disallow, Allow, Sitemap, Crawl-delay.
However, values are case-sensitive:
– User-agent: Googlebot — the bot name matching is generally case-insensitive in practice, but write it as documented to be safe.
– Paths in Disallow/Allow ARE case-sensitive. /Private/ and /private/ are different paths. This trips people up a lot — if your URLs use mixed case, your rule must match exactly.
Disallow: /Admin/ ← only blocks /Admin/, NOT /admin/
Order of directives — does it matter?
Within a record, there’s no strict required order, but the de facto/recommended convention is:
User-agent: <bot>

Disallow: <path>

Allow: <path>

Crawl-delay: <seconds>
User-agent must come first in each block — it defines which bot the following rules apply to. Everything after it (Disallow/Allow/Crawl-delay) applies until the next User-agent line starts a new block.
Rule-matching order (this is the part that actually matters)
Within a single User-agent block, specificity wins, not order of appearance. Most modern crawlers (Google, Bing) use the longest-matching-path rule, not “first match” or “last match”:
User-agent: *

Disallow: /folder/

Allow: /folder/public/
Even though Disallow comes first, /folder/public/page.html is allowed, because /folder/public/ is a longer, more specific match than /folder/.
Block-matching order (which User-agent block applies to a bot)
- The crawler looks for a block with its exact name (e.g.,
Googlebot). - If none exists, it falls back to
User-agent: *. - A bot only follows one block — the most specific one that matches it — not a cascade of all matching blocks.
Sitemap and other global directives
Sitemap: isn’t tied to any User-agent block — it can go anywhere in the file (commonly at the top or bottom) and applies globally.
Practical template order
# Specific bots first
User-agent: Googlebot
Disallow: /private/
Allow: /private/press-kit/
User-agent: GPTBot
Disallow: /
# Wildcard fallback last
User-agent: *
Disallow: /admin/
Allow: /
Sitemap: https://example.com/sitemap.xml
Summary:
– Directive names: case-insensitive, but capitalize by convention.
– Paths/values: case-sensitive — match exactly.
– No enforced order of lines, but specific bots before *, and within a block, longest path match wins regardless of Allow/Disallow order.
Where should robots.txt be placed ?
Root directory only: https://www.example.com/robots.txt
It must sit at the domain root — not in a subfolder. example.com/pages/robots.txt is ignored entirely. Each subdomain needs its own: shop.example.com/robots.txt is separate from www.example.com/robots.txt. Same for HTTP vs HTTPS and www vs non-www — they’re technically treated as different origins, so if you serve on multiple, make sure the accessible version has the file.
Why you should have robots.txt ?
- Crawl budget efficiency — Large sites especially benefit from steering crawlers away from low-value pages (admin, filters, duplicates) so Googlebot spends its limited crawl budget on pages that actually matter for rankings.
- Keep sensitive/irrelevant areas out of casual crawling — staging environments, internal tools, cart/checkout flows.
- Prevent duplicate content issues — blocking parameterized/sorted URL variants stops search engines from wasting resources crawling near-identical pages.
- Point crawlers to your sitemap — a lightweight way to make sure your sitemap gets discovered.
- Avoid server strain — on very large sites, uncontrolled bot crawling can add real load; robots.txt helps manage that.
One common misconception worth flagging: an empty or missing robots.txt doesn’t hurt your SEO — it just means “crawl everything.” You don’t strictly need one if you have nothing to restrict, but virtually every real site benefits from at least a minimal one that points to the sitemap and blocks a few low-value paths.
Here’s a well-tested robots.txt setup for a standard WordPress site:
“`
User-agent: *
Disallow: /wp-admin/
Allow: /wp-admin/admin-ajax.php
Disallow: /wp-includes/
Disallow: /wp-content/plugins/
Disallow: /wp-content/cache/
Disallow: /wp-content/themes/
Disallow: /readme.html
Disallow: /license.txt
Disallow: /trackback/
Disallow: /comments/feed/
Disallow: /?s=
Disallow: /search/
Disallow: /*?replytocom=
Disallow: /wp-login.php
Disallow: /xmlrpc.php
Sitemap: https://www.example.com/sitemap_index.xml
“`
Why each block is there
| Directive | Reason |
|---|---|
Disallow: /wp-admin/ |
Blocks the entire admin dashboard — no SEO value, and shouldn’t be crawlable |
Allow: /wp-admin/admin-ajax.php |
Many themes/plugins rely on this file loading correctly even for front-end AJAX calls — blocking it can break site functionality that Google evaluates during rendering |
Disallow: /wp-includes/ |
Core WP system files — irrelevant to crawl |
Disallow: /wp-content/plugins/ |
Plugin source folders — no content value, sometimes exposes unnecessary file structure |
Disallow: /wp-content/cache/ |
Cache-generated duplicate files |
Disallow: /readme.html, /license.txt |
Default WP files that reveal your WP version — minor security/info-disclosure hygiene |
Disallow: /trackback/, /comments/feed/ |
WordPress’s built-in trackback and comment-feed URLs create thin, duplicate content |
Disallow: /?s=, /search/ |
Internal search result pages — classic thin/duplicate content that shouldn’t be indexed |
Disallow: /*?replytocom= |
Comment-reply URL parameters WordPress generates per comment — creates massive duplicate URL variants of the same page |
Disallow: /wp-login.php |
Login page — no reason for it to be crawled |
Disallow: /xmlrpc.php |
Legacy WP API endpoint, frequently targeted by bots/attacks and has zero SEO value |
Important caveats
- Don’t block
/wp-content/themes/‘s CSS/JS subfolders if your theme serves them from there. Google needs to render your pages to evaluate mobile-friendliness and layout — blocking stylesheets/scripts can hurt rankings, not help them. The rule above blocks the theme folder broadly for hygiene, but if your rendering breaks in Google Search Console’s URL Inspection tool, allowlist the specific CSS/JS paths your theme needs, e.g.:
Allow: /wp-content/themes/*/style.css

Allow: /wp-content/themes/*/*.js
- If you use Yoast SEO or RankMath, they auto-generate a virtual robots.txt and sitemap reference — check Yoast → Tools → File Editor or RankMath → General → Sitemap before manually creating a static file, so you don’t end up with two conflicting versions.
- Replace the Sitemap URL with your actual sitemap path — Yoast uses
/sitemap_index.xml, RankMath uses/sitemap_index.xmltoo, but All in One SEO uses/sitemap.xml. Check yours directly. - Don’t add
noindexdirectives inside robots.txt — Google stopped supporting that in 2019. Use the SEO plugin’s per-page “noindex” setting instead for pages like tag archives or thin category pages. - WooCommerce sites should additionally consider blocking
/cart/,/checkout/, and/my-account/since these are functional, user-specific pages with no search value:
Disallow: /cart/

Disallow: /checkout/

Disallow: /my-account/
